Managing VM Persistence in Harvester via Longhorn Replication
Learn how Harvester uses Longhorn to provide distributed block storage for VMs, ensuring high availability through synchronous replication and dynamic volume expansion.
29 Jul 2025, 03:54 UTC
The Challenge of State in Hyper-Converged Infrastructure
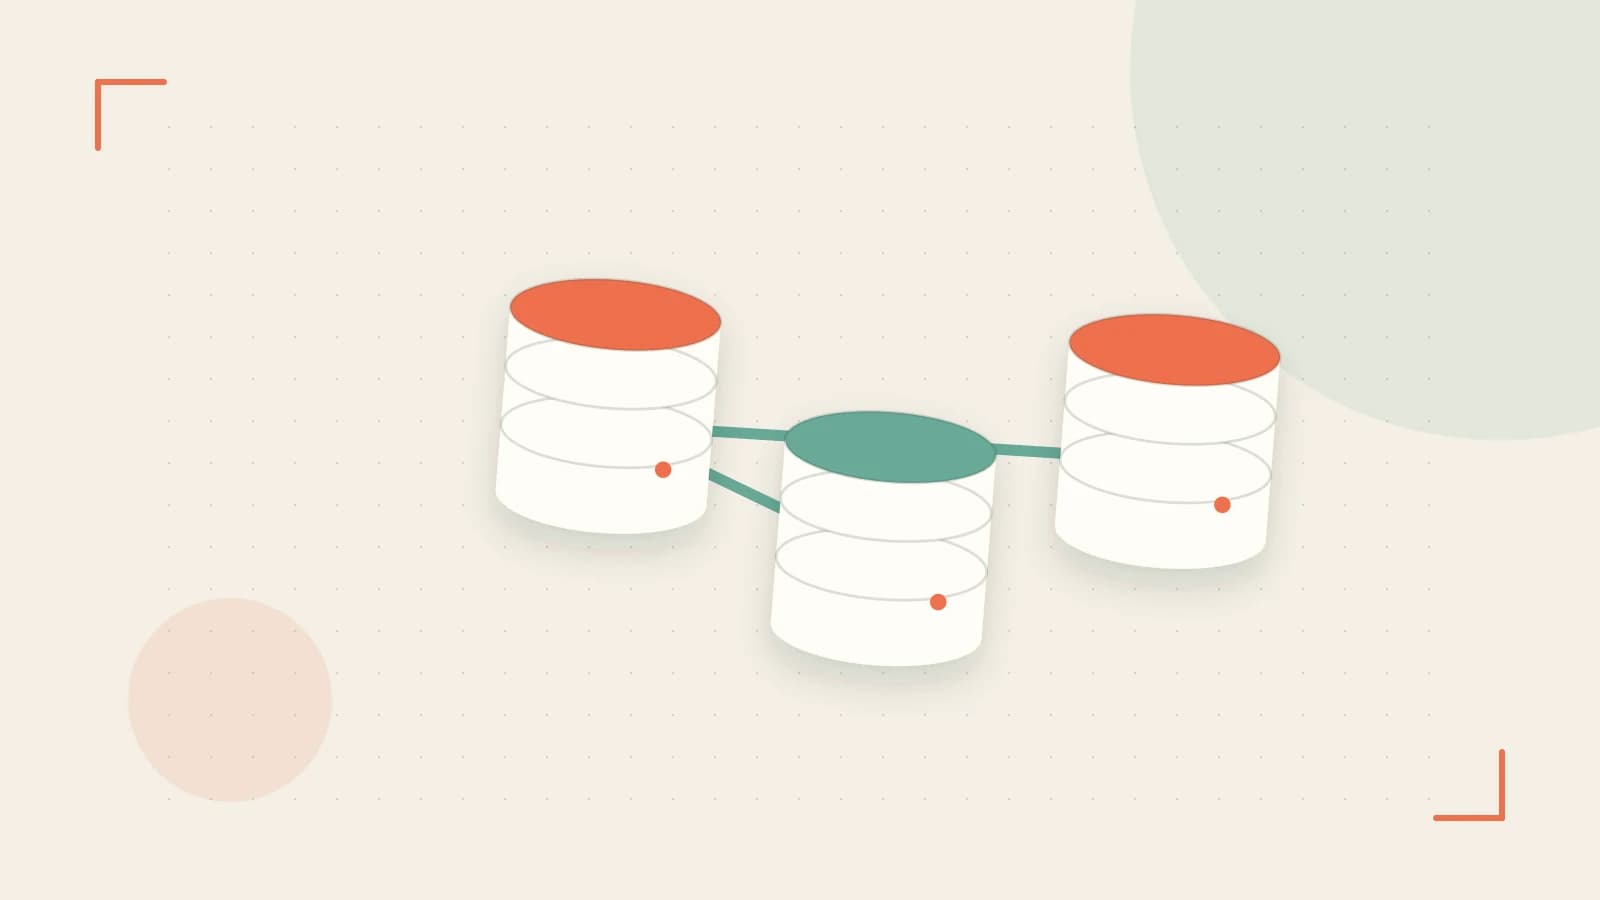
In a traditional virtualized environment, storage is often a separate entity—a SAN or NAS—that provides a central point of truth. When moving to a Hyper-Converged Infrastructure (HCI) like Harvester, the storage is distributed across the same nodes that run your Virtual Machines (VMs). The immediate problem is risk: if a physical node fails, the data residing on that node's local disks is inaccessible, potentially killing the VM and its data.
The solution in Harvester is the integration of Longhorn, a distributed block storage system. By treating VM disks as replicated volumes across the cluster, Harvester ensures that a node failure does not result in data loss or prolonged downtime.
How Harvester Maps VMs to Block Storage
Harvester doesn't use a proprietary storage format; it leverages the Kubernetes Container Storage Interface (CSI). In this architecture, every VM disk is essentially a PersistentVolumeClaim (PVC).
When you create a VM disk, Longhorn creates a volume that is replicated synchronously across multiple nodes. If you set a replication factor of 3, every write operation must be acknowledged by three different physical nodes before the operation is marked as complete. This ensures that even if two nodes fail simultaneously, the remaining node holds a consistent copy of the data, allowing the VM to be rescheduled and restarted without losing state.
Configuring Replication for High Availability
Choosing the right number of replicas is a balance between reliability and performance. While a higher replica count increases data safety, it also increases the write latency and consumes more raw disk space across the cluster.
Example: Setting Up a Replicated VM Disk
When deploying a VM through the Harvester UI or YAML configuration, the storage settings determine the redundancy level. For a production-grade database VM, a replication count of 3 is standard.
# Conceptual PVC configuration for a Harvester VM Disk
apiVersion: v1
kind: PersistentVolumeClaim
metadata:
  name: vm-disk-production-db
spec:
  accessModes: ["ReadWriteOnce"]
  storageClassName: longhorn
  resources:
    requests:
      storage: 100Gi
# Note: The actual replica count is typically managed via the
# Longhorn storage class or the Harvester UI settings.
Verification Step: To verify the replication status, navigate to the Longhorn UI integrated within Harvester. Select the volume associated with your VM; you should see the "Replica" status showing "Healthy" across the designated number of nodes.
Performance Trade-offs and Resource Contention
Because Harvester is an HCI solution, the CPU and RAM are shared between the guest VM and the storage engine (Longhorn). This introduces two primary constraints:
- Write Latency: Because replication is synchronous, the write speed of your VM is limited by the slowest network link between the participating nodes. If one node has a degraded NIC, all VMs using that replica set will experience increased I/O wait times.
- CPU Overhead: The Longhorn engine runs as a set of containers on each node. During periods of heavy I/O—such as a large database backup or a system update—you may see CPU spikes that compete with the VM's own processing needs.
Expanding Storage Without Downtime
One of the most practical advantages of this architecture is dynamic volume expansion. If a VM runs out of disk space, you can increase the size of the PVC in the Harvester dashboard. Longhorn expands the block device on the fly.
Important: While the block device expands immediately, the guest OS inside the VM must still be told to resize the filesystem. For a Linux VM, you would typically run resize2fs /dev/vda1 or xfs_growfs / after increasing the volume size in Harvester.
Practical Verification of Failover
To ensure your configuration actually provides the availability you expect, perform a controlled node failure test:
- Identify the node currently hosting the primary replica of your VM disk.
- Power down that node or disconnect its network.
- Observe the Harvester dashboard; the VM should enter a "Faulted" or "Stopping" state and then be automatically rescheduled to a healthy node.
- Verify that the VM boots and the data is intact.
Rollback: To return to a stable state, power the failed node back on. Longhorn will automatically detect the missing data and begin "rebuilding" the replicas to ensure the desired redundancy level is restored.
 harvester
0 replies
A thoughtful contribution can make all the difference. Be the first to share one.