k3OS's Declarative Config Was the Real Product — and Why It's Now a Design Study, Not a Platform
k3OS is archived, but its headline decision — an entire node defined by one versioned config.yaml — is still the right way to think about provisioning edge Kubernetes fleets.
15 Nov 2025, 04:57 UTC
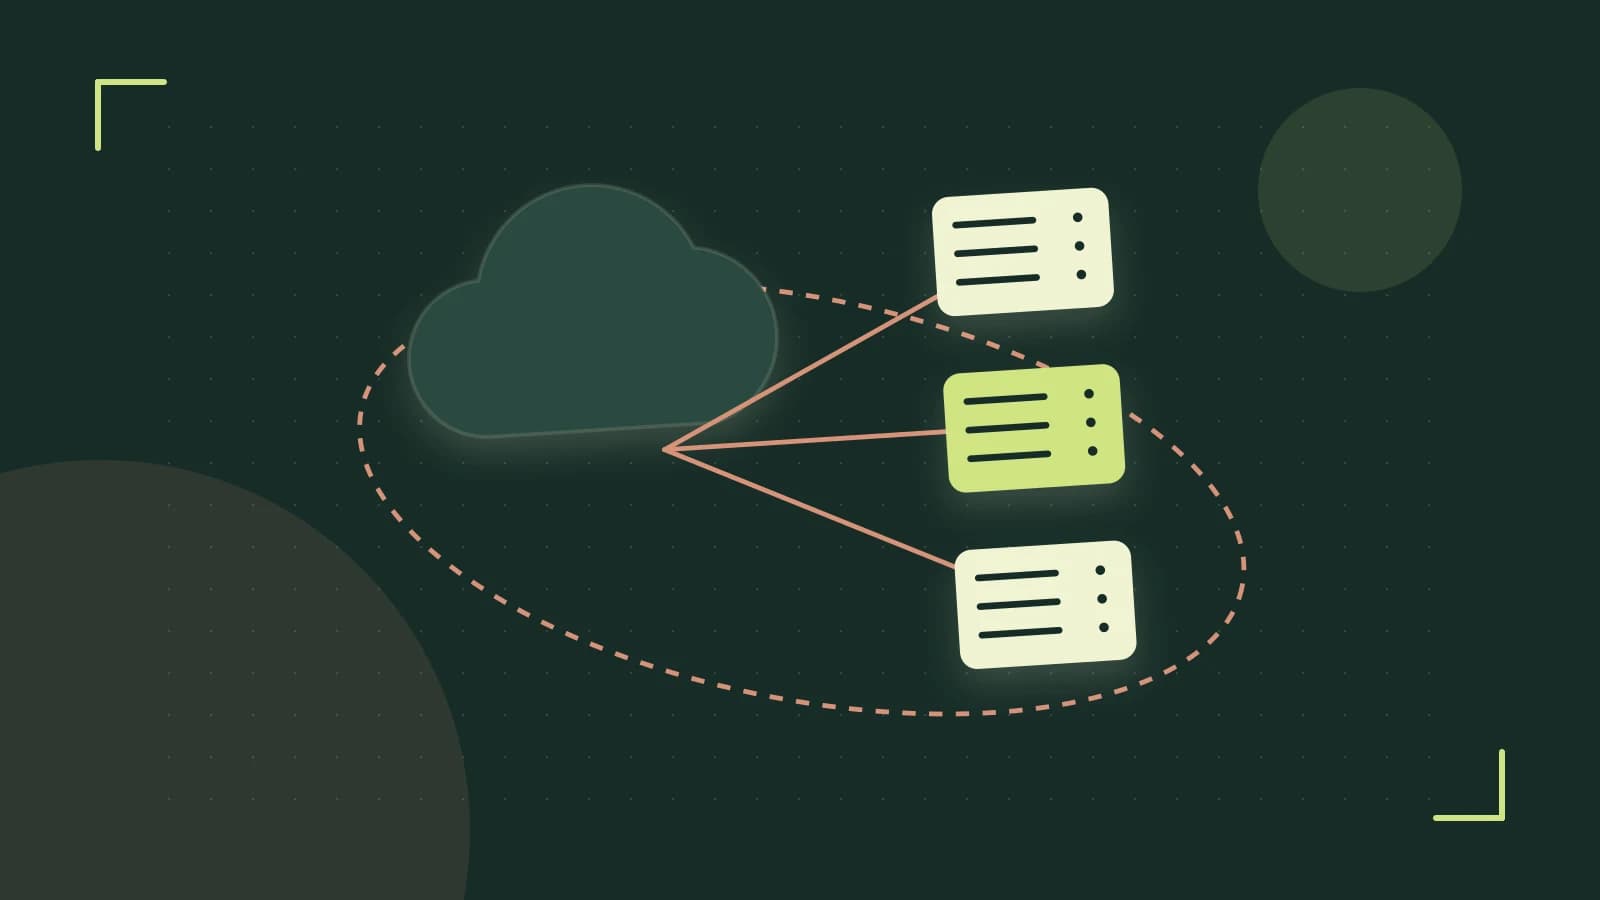
If you ever had to rack a dozen identical edge nodes, you know the pain: each one needs a hostname, network settings, SSH keys, and a Kubernetes role, and every manual step is a chance for one box to drift from the others. k3OS, Rancher's minimal Linux distribution built to run nothing but k3s, answered that with a single idea worth stealing even today: the entire node is one versioned YAML file.
Before we go further, one thing you must know: k3OS is archived and no longer maintained. Rancher pointed users toward successor projects like Elemental for new edge deployments. So read this as a design study — the engineering decision behind k3OS is still instructive, and the config pattern shows up in its successors — not as a recommendation to install it in production.
The decision: configure the OS like you'd configure a cluster
Most Linux provisioning is imperative: boot an installer, click through or script a sequence of steps, then mutate the running system with a package manager forever after. k3OS went the other way. You write a config.yaml once, check it into Git, and every node installed from it converges to the same declared state: hostname, authorized SSH keys, network interfaces, and whether the machine joins k3s as a server or an agent.
That file is applied at install time (k3os install) or read from removable media / a data source at boot, cloud-init style. The payoff is repeatability: node 7 and node 70 are byte-for-byte the same intent, and "what is this machine supposed to be?" has a diffable answer.
Immutable-ish upgrades, no package manager
The second half of the design is what k3OS left out. There was no apt or dnf workflow. Upgrades replaced the active system image rather than patching packages in place, which kept configuration drift near zero across a fleet. Day-two operations were pushed into Kubernetes itself — if you needed a tool on the host, the expected answer was "run it as a workload," not "install it on the OS." That keeps the host surface tiny and auditable, at the cost of making host-level debugging awkward when something goes wrong below the kubelet.
Worked example: one file, zero-touch node
A representative config.yaml for an agent node looks conceptually like this (verify the exact schema against the archived repository's documented examples — keys and layout changed across releases):
ssh_authorized_keys:
  - ssh-ed25519 AAAA... [contact removed]
hostname: edge-node-07
k3os:
  k3s_args:
    - agent
    - "--server"
    - "https://10.0.0.10:6443"
    - "--token"
    - "YOUR_CLUSTER_TOKEN"
  install:
    device: /dev/sda
    silent: true
Run the install from the live environment on the target machine (or a VM first — strongly recommended), as root, pointing at the config. After reboot, the expected result is: the node comes up with the declared hostname and static network config, accepts your SSH key, and appears in kubectl get nodes on the server — with no interactive setup at all. If the node doesn't appear, check the token and server URL first; those are the usual culprits.
The trade-off that bites: declarative mistakes are headless mistakes
The same property that makes the model powerful makes errors expensive. A typo'd static IP or wrong gateway in config.yaml doesn't fail loudly at a desktop — it leaves a headless edge box unreachable, and recovery options were thinner than on a general-purpose distro. Practical mitigations: validate every config in a VM before touching hardware, keep console or out-of-band access for the first boot of any new config revision, and change one thing per commit so a bad rollout has an obvious revert.
What to take away
k3OS itself is legacy — confirm the archived status and successor pointers on the GitHub repository before relying on anything here. But its core decision aged well: treat node identity as data, provision from versioned files, and replace rather than mutate. If you're evaluating Elemental, Talos, or any immutable edge OS today, you're really evaluating how well they execute that same idea. Prototype one node from a single config file, reboot it, and check that reality still matches the declaration — that test tells you more than any feature matrix.
 k3s
 k3os
0 replies
A thoughtful contribution can make all the difference. Be the first to share one.