Implementing Single-Writer Consistency with Akka Cluster Sharding
Learn how to use Akka Cluster Sharding to ensure single-writer consistency across distributed nodes, preventing race conditions in stateful applications.
30 Mar 2026, 02:30 UTC
The Problem: Distributed State Race Conditions
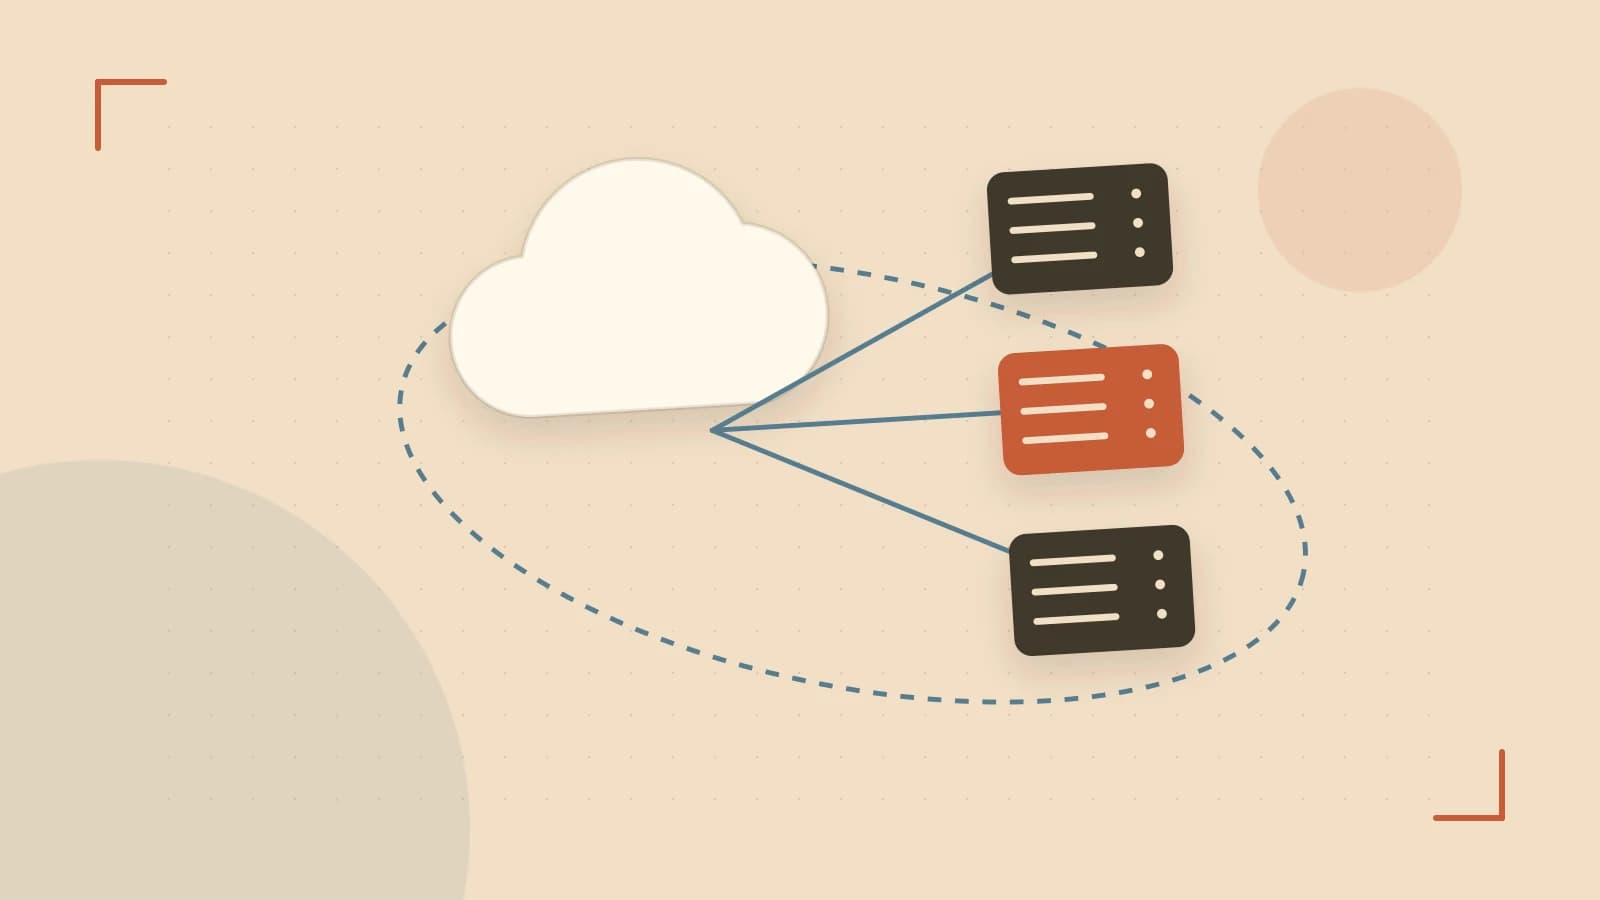
When scaling a stateful application across multiple nodes, the primary challenge is ensuring that only one instance of a specific entity (e.g., a user session, a shopping cart, or a device twin) processes updates at any given time. If multiple nodes modify the same entity state simultaneously, you encounter race conditions and data corruption.
The takeaway is to use Akka Cluster Sharding to guarantee that a unique entity ID maps to exactly one actor instance across the entire cluster, effectively creating a distributed single-writer lock without the overhead of a global distributed lock manager.
The Smallest Suitable Design
To implement this, you need three primary components working in tandem: the Entity, the ShardRegion, and the ShardCoordinator.
- Entity: The actor that holds the actual state and processes commands.
- ShardRegion: A local proxy on every node. It intercepts messages and routes them to the correct node where the entity currently resides.
- ShardCoordinator: A singleton actor that tracks which shards (groups of entities) are hosted on which nodes.
The system works by hashing the Entity ID to a Shard ID. The ShardRegion asks the Coordinator where that Shard ID lives, then forwards the message to the target node. This removes the need for the sender to know the physical location of the state.
Trust and Data Boundaries
In a sharded architecture, the entity actor is the sole authority for its state. The boundary is defined as follows:
- External Boundary: Messages arriving at the ShardRegion are treated as untrusted commands. They should be validated for schema and permission before being applied to the state.
- Internal Boundary: Once a message reaches the entity actor, it is processed sequentially. Because Akka actors process one message at a time, the entity state is modified in a thread-safe manner without requiring synchronized blocks or volatile variables.
Implementation Example: Entity Configuration
Assuming Akka Typed (version 2.6+), you define the sharding behavior using an Entity definition. This configuration tells the cluster how to extract the ID and how to create the actor.
// Run this on all nodes in the cluster with cluster-sharding dependency
val TypeKey = EntityTypeKey[Command]("UserEntity")

val entity = Entity(TypeKey) {
  entityContext =>
    entityContext.entityId -> { entityId =>
      // The actual actor behavior
      UserActor.apply(entityId)
    }
}

// To send a message from any node:
val shardRegion = ClusterSharding.get(system).entityRefFor(TypeKey, "user-123")
shardRegion ! UpdateProfile(newEmail = "tech@example.com")
Risk: If you use a non-uniform hashing algorithm or a skewed set of Entity IDs, you will create "hot shards," where one node handles 90% of the traffic while others remain idle.
Operational Checks and Verification
To verify that sharding is functioning and entities are distributed, you must monitor the ShardCoordinator. You can check the distribution by logging the local address of the actor processing the request.
Verification Steps
- Deploy the application to at least three nodes.
- Send messages to 100 different Entity IDs.
- In the entity actor's
receiveblock, log:logger.info("Entity {} processing on node {}", entityId, system.cluster.selfAddress). - Confirm that the logs show different node addresses for different IDs.
- Perform a manual shutdown of one node. Observe the logs of the remaining nodes to verify that the ShardCoordinator migrates the orphaned entities to the healthy nodes.
Failure Modes
| Failure Scenario | System Response | Impact |
|---|---|---|
| Node Crash | Coordinator detects failure; re-allocates shards to remaining nodes. | Temporary unavailability of entities during migration. |
| Network Partition | Split-brain scenario; two nodes may believe they host the same shard. | Potential for duplicate writers unless a Split Brain Resolver (SBR) is configured. |
| Heap Exhaustion | Too many active entities loaded into memory. | Increased GC pauses and slow rebalancing times. |
When to Change This Design
Cluster Sharding is optimized for strong consistency (one writer). You should pivot to a different architecture if:
- Eventual Consistency is Sufficient: If you can tolerate stale reads and concurrent writes, a replicated data store (like Cassandra or DynamoDB) is more performant as it removes the ShardCoordinator bottleneck.
- Extreme Scale: If the ShardCoordinator becomes a bottleneck due to the sheer volume of shard migrations, consider manual partitioning or a more decentralized routing mechanism.
- Statelessness: If the entity state can be fully derived from a database on every request, the complexity of sharding is unnecessary; use a standard load balancer.
 akka
 scala
0 replies
A thoughtful contribution can make all the difference. Be the first to share one.