Horizontal Auto-Scaling on Scalingo: The Engineering Decisions Before You Flip the Switch
Scalingo's horizontal auto-scaling adds containers under load, but session state, database pools, and cold starts decide whether it helps or hurts. Here is how to size a policy safely.
15 Sept 2025, 06:48 UTC
The 3 a.m. latency spike that has nothing to do with your code
Your API is humming along at 50 requests per second. Then a partner integration goes live, traffic jumps to 400, and p95 latency climbs from 120 ms to 4 seconds. The code hasn't changed. The database is fine. You need more compute, fast. On Scalingo, the obvious lever is horizontal auto-scaling—adding identical containers behind the load balancer. But the obvious lever is also the one that snaps if your application still holds session state in memory or opens a database connection per container without a ceiling.
Horizontal auto-scaling on Scalingo is a capacity tool, not a magic fix. It works when your application runtime is stateless and your downstream resources are sized for the maximum container count you allow. This piece walks through the mechanics, the failure modes, and a concrete policy you can adapt.
How Scalingo's horizontal auto-scaling actually works
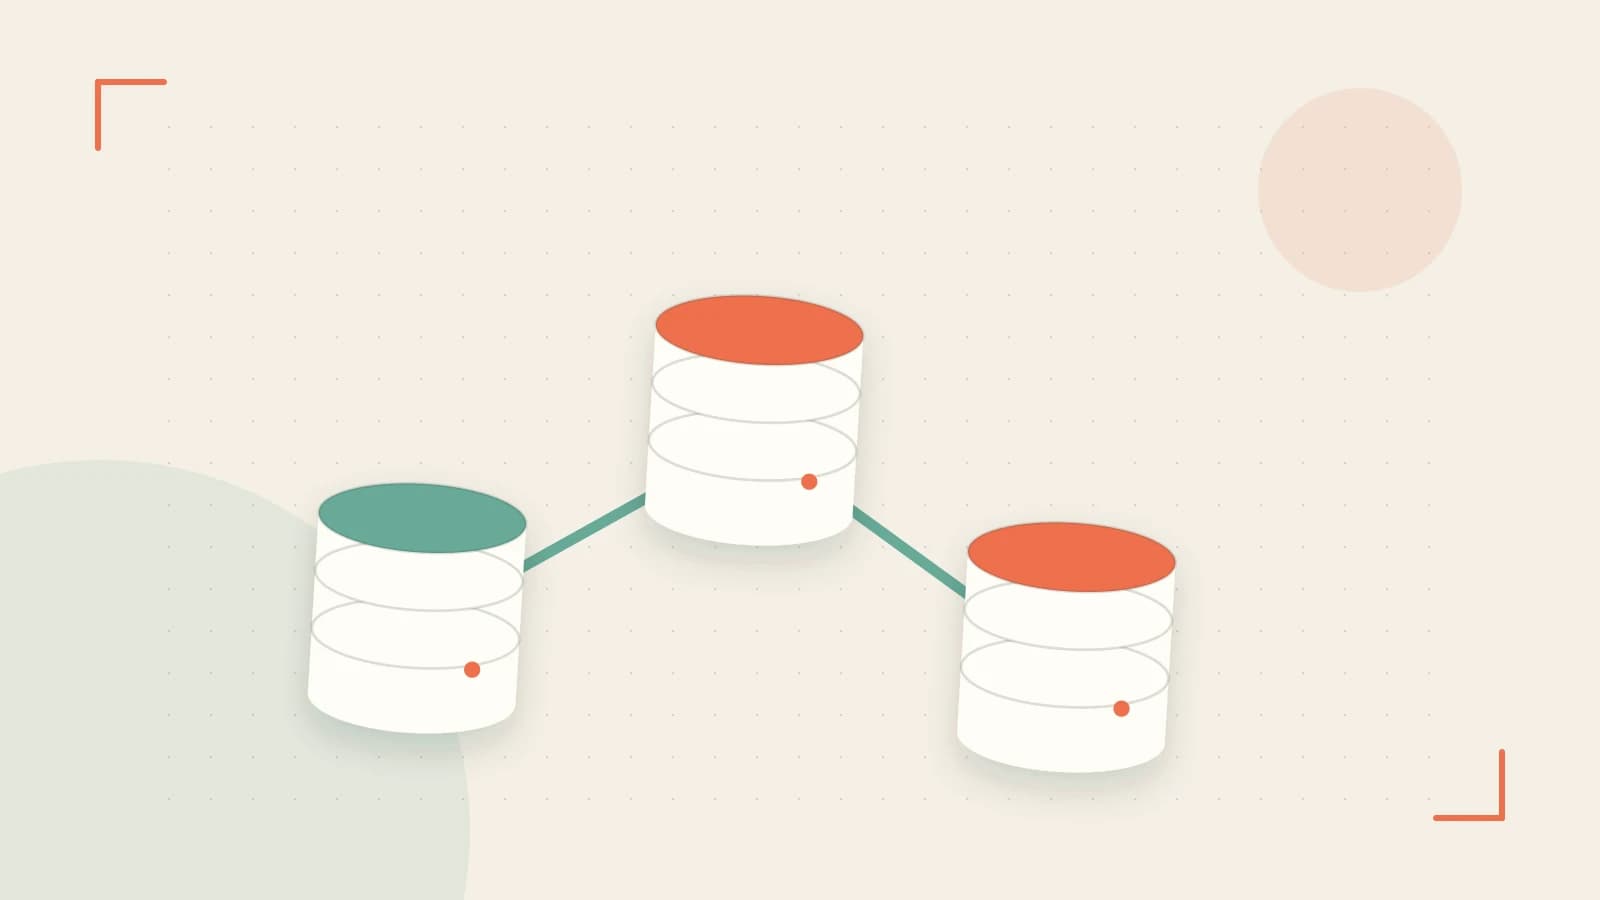
Scalingo runs your application inside containers (sometimes called dynos in PaaS terminology). Horizontal auto-scaling watches a metric—typically CPU utilization or memory—and adjusts the number of running containers within bounds you define. When traffic rises, the orchestrator provisions new copies of the same container image and the load balancer distributes requests across them. Because Scalingo separates the application runtime from persistent storage, adding containers does not fragment your data; the filesystem or database remains shared. What changes is only the compute layer.
That separation is the platform's core promise: scale the stateless web tier freely while your stateful data stays put. The catch is that your application must actually be stateless for this to hold.
The statelessness tax: sessions, pools, and cold starts
Before you enable a policy, audit your application for state. If sessions live in local memory, a user logged in on container A will be logged out when the load balancer routes their next request to container B. Rapid scale-out makes this worse because the container set churns. The standard fix is an external session store—Redis or a database-backed session—so any container can serve any request.
Two other limits bite during spikes:
- Cold starts. A newly provisioned container needs time to boot and warm caches. If your scale-up threshold is too tight, users will hit slow responses before the new container is ready.
- Database connection pools. If your application opens five connections per container and your database allows 100 total, you cannot safely run more than 20 containers. Auto-scaling without a connection ceiling turns a traffic spike into a database outage.
A worked example: sizing a policy around your database pool
Consider a Rails API running on Scalingo with two fixed containers. Your PostgreSQL instance has max_connections set to 100. The application's connection pool is configured for 5 connections per process. A naive auto-scaling policy might allow 20 containers, but 20 × 5 = 100 connections leaves no headroom for admin tasks or other services. A safer policy sets a maximum of 12 containers, using at most 60 connections.
You configure this in the Scalingo dashboard under your application's scaling or resources section (verify the exact label in current documentation). Set the minimum containers to 2 so you retain redundancy, the maximum to 12, and the target CPU threshold to 70 percent. The exact threshold depends on your application's profile; a CPU-bound worker might need a lower target, while an I/O-bound service can tolerate higher CPU before scaling.
To test, run a load generator from your local machine or a CI runner:
ab -n 10000 -c 100 https://your-app.scalingo.io/endpointExpected check: the container count in the Scalingo dashboard rises above 2, and response times stabilize rather than continuing to climb. Risk: if the database rejects connections because the pool is undersized, you will see connection errors in application logs. If that happens, lower the maximum container count or increase the database connection limit before re-enabling the policy.
Verification and rollback
After configuring the policy, verify it in two ways. First, watch the container count in the Scalingo dashboard during a controlled load test; it should move within your min and max bounds. Second, check your application logs for session errors or database connection failures. If the policy misbehaves—scaling too aggressively or exhausting downstream resources—disable it and return to a fixed container count. That rollback is a state change, so do it during a maintenance window or after traffic subsides.
Auto-scaling is not a set-and-forget feature; revisit the thresholds whenever you change your database plan, connection pool size, or application architecture.
Start conservative
Begin with a conservative maximum, an external session store, and a load test that actually triggers a scale event. If those three hold, horizontal auto-scaling on Scalingo buys you headroom without surprises.
 scalingocontainer-orchestrationhorizontal-auto-scalingstateless-architecture
0 replies
A thoughtful contribution can make all the difference. Be the first to share one.