Architecture Note: Tail Sampling with the OpenTelemetry Collector
A two-tier OpenTelemetry Collector design: local agents export OTLP to a gateway that runs tail_sampling, preserving errors and slow traces while bounding cost and blast radius.
12 Aug 2025, 22:14 UTC
The problem: keeping errors without paying for every span
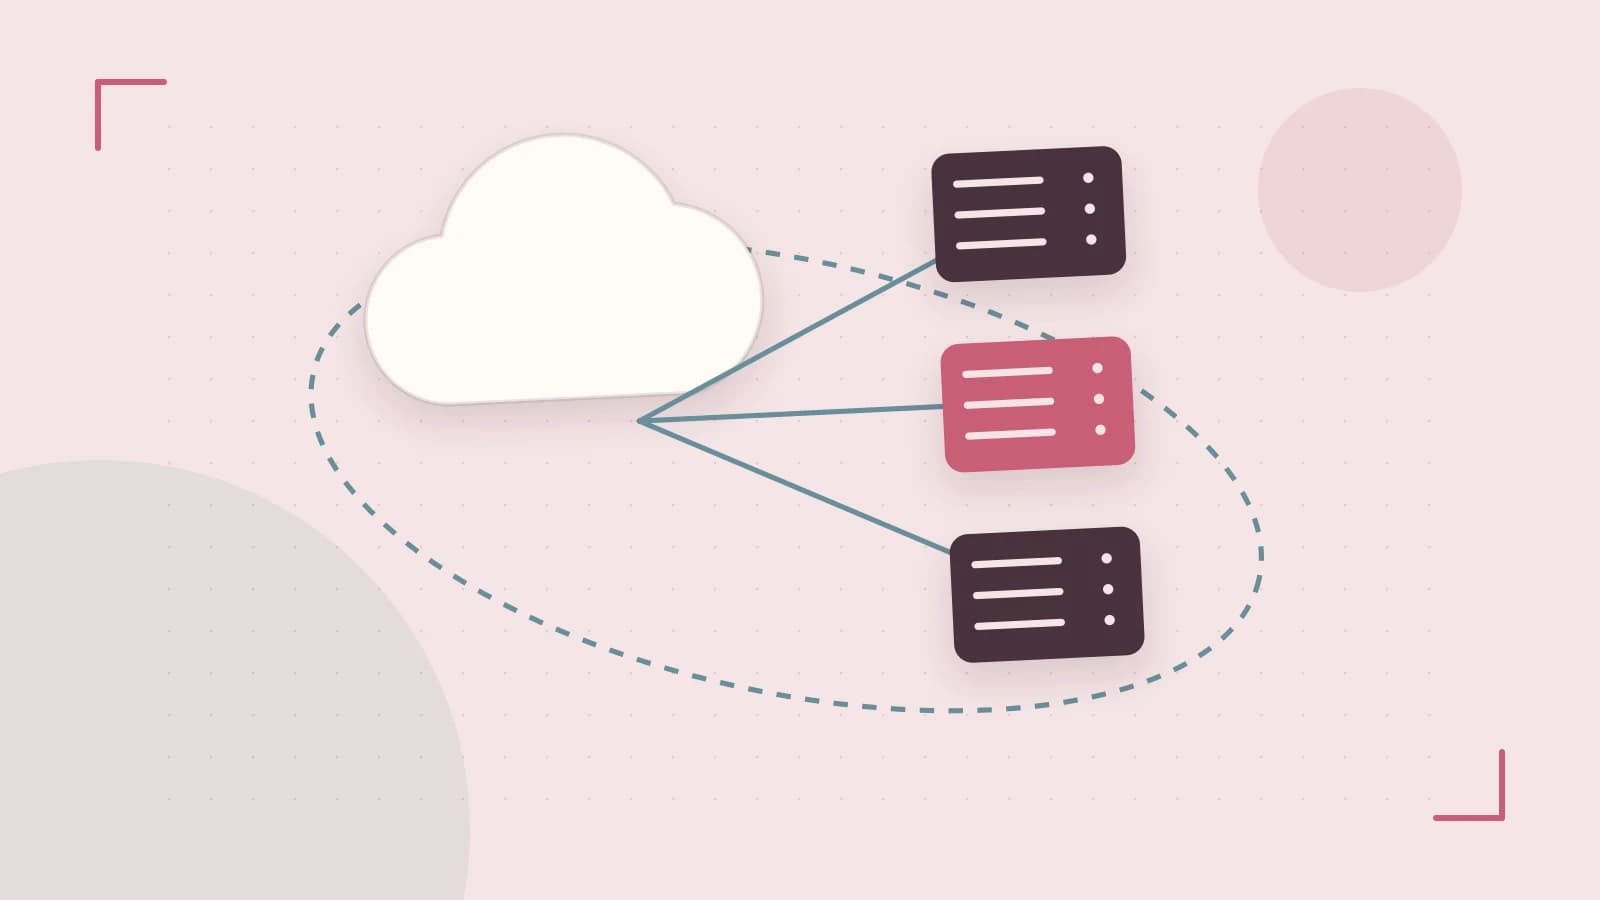
Teams often turn on distributed tracing and then face a storage cliff. Head-based sampling in the SDK can reduce volume, but it discards traces before the application knows whether a request failed or ran slowly. Tail sampling inside an OpenTelemetry Collector keeps the decision open until a trace is complete, so you can preserve every error and every request above a latency threshold while sampling only a small fraction of normal traffic. The useful takeaway is architectural: place lightweight agent Collectors inside the application trust boundary, centralize tail sampling in a gateway Collector, and enforce authentication and attribute filtering at that gateway.
Requirements for a tail-sampling pipeline
Before choosing components, fix the requirements. The pipeline must reduce span volume without losing error statuses or high-latency traces. It must make one sampling decision per trace, not per span. It must bound both cost and blast radius, so a single failure does not silently erase telemetry across every service. Finally, it must keep the telemetry data plane separate from the application security boundary, because a Collector is not a security control.
The smallest suitable design: agent plus gateway
The smallest design that meets these requirements uses two tiers. Each node or service runs an agent Collector with an OTLP (OpenTelemetry Protocol) receiver, a memory_limiter processor, a batch processor, and an OTLP exporter pointed at a central gateway. The gateway Collector receives OTLP, applies the tail_sampling processor, batches again, and exports to one or more backends.
Agents should not run tail_sampling. An agent usually sees only the spans produced by its local workload, not the full trace across upstream and downstream services. Sampling a partial trace produces incomplete decisions and broken waterfalls. Agents also should not hold backend credentials; they export to the gateway, and the gateway owns the backend connection.
A representative agent configuration looks like this:
receivers:
  otlp:
    protocols:
      grpc:

processors:
  memory_limiter:
    limit_mib: 512
    check_interval: 1s
  batch:

exporters:
  otlp/gateway:
    endpoint: gateway-host:4317
    tls:
      insecure: false

service:
  pipelines:
    traces:
      receivers: [otlp]
      processors: [memory_limiter, batch]
      exporters: [otlp/gateway]
Verify every field against your pinned Collector distribution; processor names and defaults have changed across releases.
Trust and data boundaries
Agents sit close to workloads but remain inside the application trust boundary. They should not authenticate to observability backends. Terminate TLS or mTLS (mutual TLS) and authentication at the gateway instead. Before the gateway exports to a backend, allowlist or strip sensitive attributes. Treat any attribute emitted by an agent as untrusted input to sampling policy: a compromised or misconfigured workload could otherwise influence sampling decisions by setting trace attributes.
Sampling policy and trace routing
Start with three policies on the gateway. First, always keep traces whose root or any span has an error status. Second, always keep traces whose latency exceeds a threshold, for example one second. Third, sample a small percentage of everything else. The exact policy names and fields depend on your Collector build, but the intent is stable.
Tail sampling requires all spans for a trace to arrive at the same gateway instance, or at a consistent routing group that can share trace state. If a load balancer spreads spans for one trace across independent gateways, each instance sees a partial trace and the decision is unreliable. Keep policy keys low-cardinality and ensure trace context is propagated consistently across services.
A representative gateway pipeline:
receivers:
  otlp:
    protocols:
      grpc:
        endpoint: 0.0.0.0:4317

processors:
  tail_sampling:
    decision_wait: 10s
    num_traces: 50000
    expected_new_traces_per_sec: 1000
    policies:
      - name: errors-policy
        type: status_code
        status_code:
          status_codes: [ERROR]
      - name: slow-policy
        type: latency
        latency:
          threshold_ms: 1000
      - name: baseline-policy
        type: probabilistic
        probabilistic:
          sampling_percentage: 5

exporters:
  otlp/backend:
    endpoint: backend-host:4317
    tls:
      insecure: false

service:
  pipelines:
    traces:
      receivers: [otlp]
      processors: [tail_sampling]
      exporters: [otlp/backend]
Treat this as illustrative only. Confirm that the tail_sampling processor is stable in your distribution and that field names such as decision_wait, threshold_ms, and sampling_percentage match your version.
Operational checks
Monitor the Collector's own telemetry. Watch for receiver refused or dropped spans, exporter failures, queue depth, memory_limiter pressure, and tail_sampling sampled versus dropped counts. A rising queue depth or memory_limiter refusal means the gateway is saturated before it can make sampling decisions.
Also run an end-to-end check: generate a known trace containing an error span and a known trace containing a slow span, then confirm both arrive in the backend. Generate a batch of normal traces and confirm only the expected fraction arrives. This validates the policy, not just the pipeline.
Failure modes and blast radius
A gateway outage or overload drops traces after agents have already accepted them. Agents buffer briefly, but once their queues fill they drop spans. Tail sampling itself increases memory use and decision latency because incomplete traces are held until decision_wait expires. Clock skew or inconsistent trace attributes can produce bad decisions: a slow span may arrive after the decision window closes. Traffic bursts may cause queue drops instead of useful backpressure, so default queue and batch sizes are often too small for production.
Conditions that change the design
This design fits when you need cost control with error and latency preservation. It stops fitting under several conditions. Strict audit or full-fidelity requirements may make any sampling unacceptable, pushing the decision to the SDK or the backend. Multi-tenancy may require per-tenant gateways or routing groups to isolate noisy neighbors. Very high attribute cardinality can overwhelm tail sampling memory, so reduce cardinality before the gateway. If you need tight metrics and logs correlation, ensure the sampling policy does not break trace IDs for correlated signals. Vendor-specific sampling features may be cheaper or more accurate than a self-managed gateway, in which case move sampling to the backend.
Practical verification
Validate the configuration before deploying. On the host where the Collector binary runs, use its built-in validation:
otelcol validate --config=/etc/otelcol/config.yamlRun this on both agent and gateway hosts. Required permissions are read access to the config file. The expected check is a clean exit with no errors. The risk is that validation checks syntax, not runtime behavior.
In staging, replace the backend exporter with a debug exporter and inspect payloads for PII (personally identifiable information) or secrets. Generate known error and slow traces, then confirm the backend keeps all targeted traces and only the expected fraction of normal traces. Load test with bursts and a simulated gateway outage; measure dropped spans, queue depth, memory use, and recovery after reconnect. If the gateway cannot recover or drops targeted traces, revisit decision_wait, queue sizes, and the number of gateway replicas before production.
 opentelemetry
0 replies
A thoughtful contribution can make all the difference. Be the first to share one.