When Spark’s Broadcast Hash Join Saves You Time (and Money)
Broadcast Hash Join cuts join latency by eliminating shuffles when one side is small. Learn when to enable it, how to force it, and the trade‑offs to watch for in real‑world Spark jobs.
19 Oct 2025, 21:46 UTC
Problem: Shuffling is the Silent Performance Killer
In Spark SQL, a join normally triggers a shuffle – data is redistributed across the cluster to align matching keys. This involves disk I/O, network traffic, and a second round of work for each executor. For a 500 MB fact table joined with a 5 MB dimension table, the shuffle can dominate the runtime, especially on network‑constrained clusters.
Thesis: Broadcast the Tiny Side, Eliminate the Shuffle
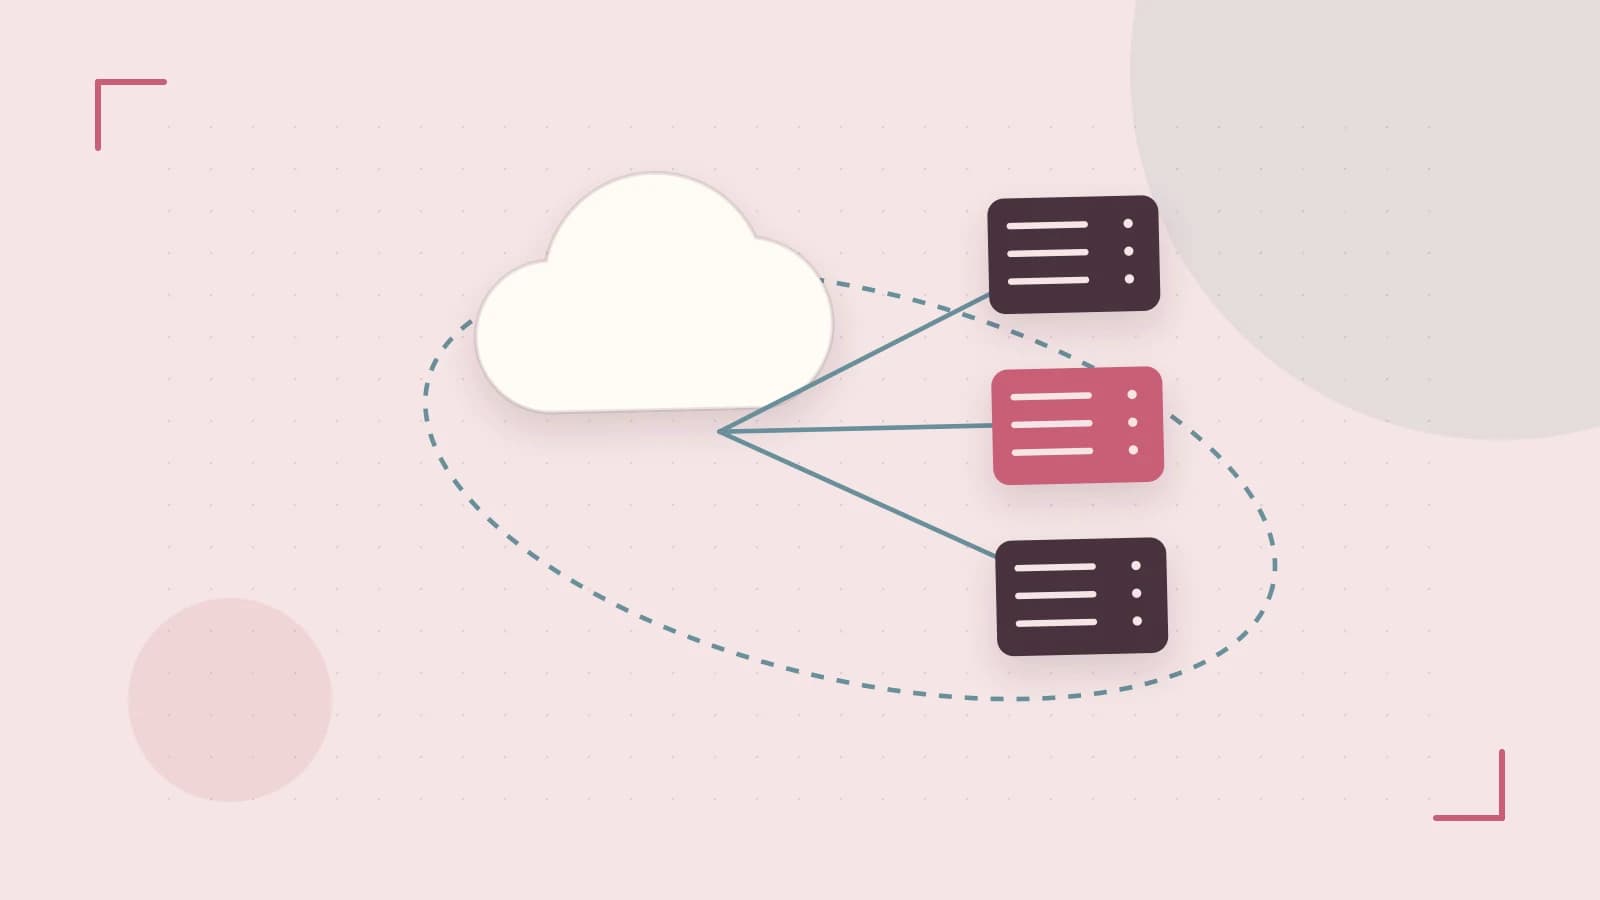
When one side of a join is small enough to fit in the driver’s memory, Spark can broadcast that side to every executor. Each executor then builds a local hash table and performs the join in place, avoiding the shuffle entirely. The default threshold is 10 MB, but you can tune it for your workload.
How Spark Decides to Broadcast
- Automatic: Spark’s optimizer rule
BroadcastHashJoinExectriggers when the size of a table is belowspark.sql.autoBroadcastJoinThreshold(default 10 MB). - Explicit Hint: Use
/*+ BROADCAST(t2) */in the SQL to force a broadcast regardless of size. - Disable: Set
spark.sql.autoBroadcastJoinThresholdto-1to turn off broadcasting entirely.
Concrete Example: 5 MB Dimension + 500 MB Fact
Assume you have two Hive tables: dim_customer (~5 MB) and fact_sales (~500 MB). You want to join on customer_id.
# Start a Spark session
spark = SparkSession.builder.appName("BroadcastJoinDemo").getOrCreate()

# Optional: adjust broadcast threshold if needed
spark.conf.set("spark.sql.autoBroadcastJoinThreshold", "15MB")

# Query without hint – will use shuffle hash join
query1 = """
SELECT /*+ BROADCAST(dim_customer) */
  f.*,
  d.customer_name
FROM fact_sales f
JOIN dim_customer d ON f.customer_id = d.customer_id
"""

# Show the execution plan
print("Plan with broadcast hint:\n", spark.sql(query1).explain(true))

# Run the query and measure time
start = time.time()
result = spark.sql(query1).count()
print("Rows returned:", result, "Time (s):", time.time() - start)
When you run the same query without the BROADCAST hint, the explain(true) output will show a ShuffleHashJoinExec node. With the hint, the plan shows BroadcastHashJoinExec and no shuffle stage. The difference in execution time can be an order of magnitude for this data size.
Trade‑offs & Limitations
- Driver Memory: The broadcasted table is stored in the driver’s heap. If the table grows beyond the threshold, you risk
OutOfMemoryError. Monitor driver memory in the Spark UI and adjustspark.driver.memoryor the threshold accordingly. - Read‑Only & Reuse: Broadcasting is most effective when the small table is read‑only and reused across multiple stages or jobs. If the table changes frequently, you may incur additional disk reads for each broadcast.
- Cardinality & Skew: Broadcast joins assume that the broadcasted table can be joined locally. If the join key has high cardinality or severe skew, a shuffle may still be needed to balance the data.
- Cluster Size: In very large clusters, broadcasting the same data to every executor can increase memory pressure. Use the hint sparingly and consider caching the small table if it will be reused.
Actionable Checklist for Practitioners
- Identify joins where one side is naturally small (e.g., lookup tables, configuration tables).
- Verify size: use
spark.read.table("name").count()andrdd.mapPartitionsIter(…).take(1).sizeto estimate bytes. - Set
spark.sql.autoBroadcastJoinThresholdappropriately; start with the default 10 MB and adjust if you see OOM or sub‑optimal plans. - Use the
BROADCASThint for critical joins you want to guarantee broadcast, but monitor driver memory. - Cache the small table with
df.cache()if it will be joined repeatedly to avoid repeated disk reads. - After each change, run
explain(true)to confirm that the plan usesBroadcastHashJoinExecand that the shuffle stage is gone. - In production, set
spark.sql.autoBroadcastJoinThresholdto a value that balances memory usage and performance; consider using a dynamic threshold per job if your cluster supports it.
By following these steps, you can dramatically reduce join latency for the right workloads, cutting both I/O and network overhead while keeping cluster resources in check.
 apachespark
0 replies
A thoughtful contribution can make all the difference. Be the first to share one.