DRS Automation Level and Threshold: The Engineering Trade-Offs That Actually Matter
DRS can rebalance a vSphere cluster with vMotion, but the real engineering choice is automation level and migration threshold. Learn how to size for maintenance and avoid vMotion churn.
08 Feb 2026, 11:12 UTC
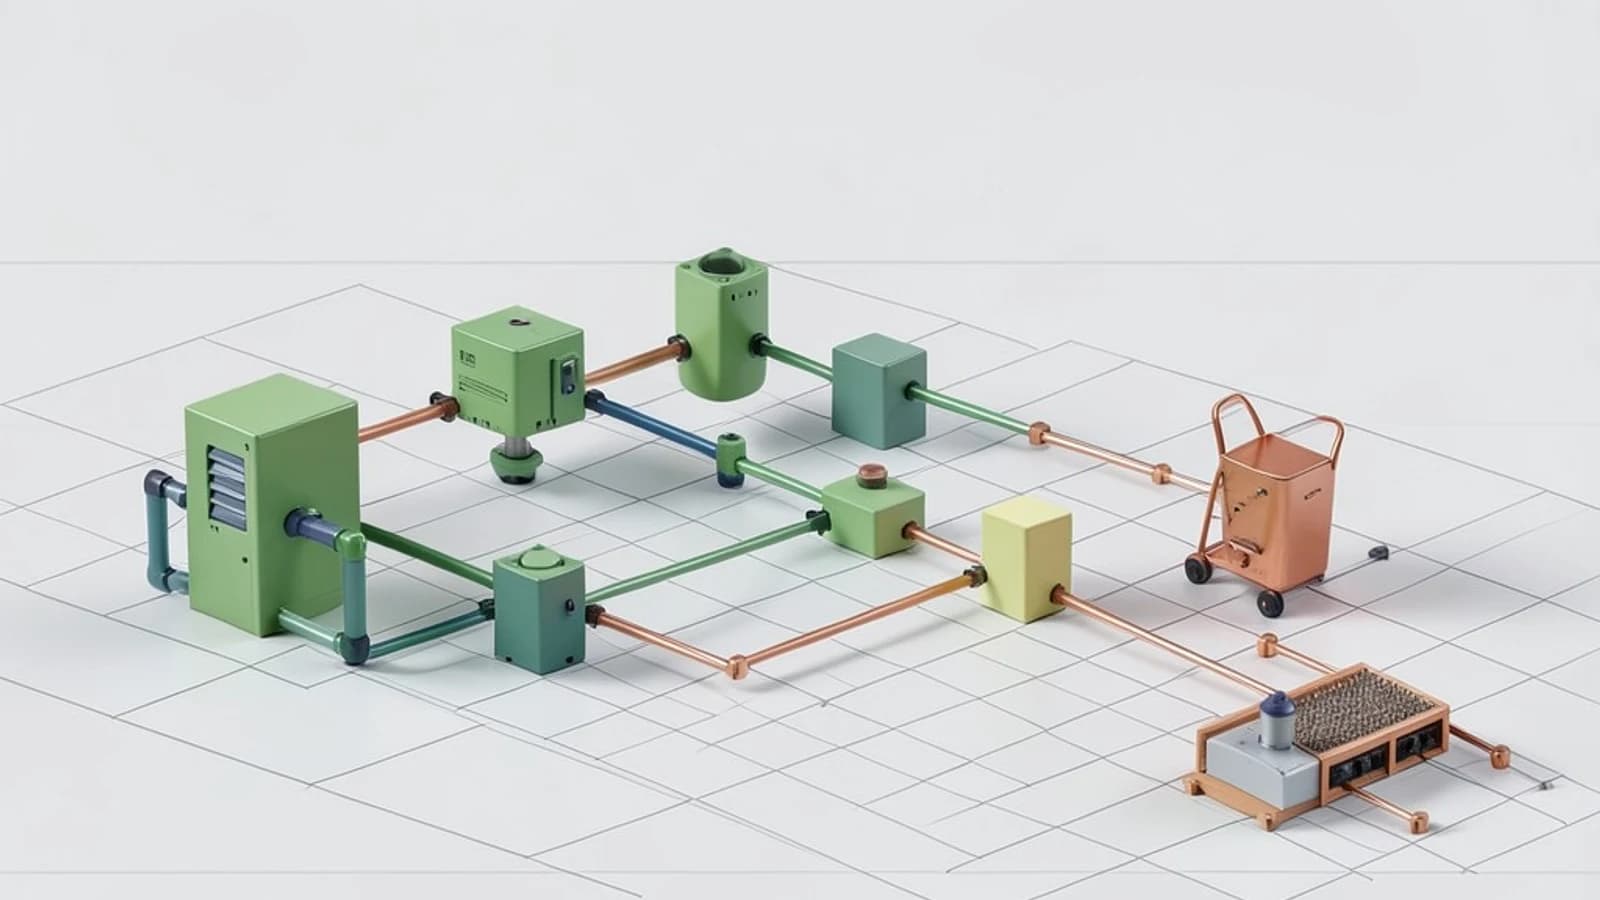
One host in the cluster is pegged at 90% CPU while the others sit at 30%. DRS can fix that with vMotion, but the real decision is how much it should fix, when, and whether you let it act without review. The useful takeaway is that DRS automation level and migration threshold are capacity and operational choices, not just toggles.
DRS balances demand, not just capacity
Distributed Resource Scheduler continuously evaluates CPU and memory demand across ESXi hosts in a vSphere cluster and uses vMotion to live-migrate running VMs so no single host becomes a hotspot. vMotion moves a powered-on VM between hosts with no application downtime, using a dedicated VMkernel network.
The engineering decision is automation level. Manual and Partially Automated modes generate recommendations only. Fully Automated applies placements and migrations. Many teams start Partially Automated to build trust and learn which workloads DRS wants to move, then move to Fully Automated for steady-state clusters.
Threshold controls how reactive DRS is
The migration threshold slider sets how much imbalance DRS tolerates before acting, from conservative to aggressive. Conservative means DRS waits for larger imbalances; aggressive triggers moves on smaller differences.
An aggressive setting can cause frequent vMotion storms on bursty workloads. Each migration consumes network bandwidth and host CPU, so reaction latency rises if the vMotion VMkernel is shared or undersized. A fast network for vMotion, typically 10 GbE or better, materially shortens migration time and reduces DRS reaction latency.
Practical check: in vSphere Client open Cluster > Monitor > vSphere DRS. Review the DRS summary and migration history. A healthy setting produces occasional migrations that reduce imbalance without constant churn. If you see repeated moves of the same VMs, soften the threshold or set a VM override.
Affinity rules help, then get in the way
DRS affinity and anti-affinity rules let you express placement preferences. Keep VMs together for low-latency pairs, or keep replicated nodes apart. Rules can be should or must.
Overusing must rules can block maintenance mode evacuations and HA restarts. Anti-affinity rules are preferences, not guarantees. During a host failure, HA may violate should rules to restore service. Design capacity assuming rules may be violated under failure.
Sizing for maintenance and failover with DRS and HA
DRS works alongside vSphere HA. Admission control and N+1 host sizing ensure the cluster can absorb a host failure.
Worked example for sizing. A 5-host cluster intended for maintenance and failover. Target each host at roughly 60-70% steady utilization so the workload of one host fits on the remaining four. That leaves headroom for DRS to rebalance during planned maintenance and for HA to restart VMs after an unplanned loss.
To validate the design, place a host into maintenance mode in a test environment and confirm all VMs evacuate via vMotion without downtime and without violating your affinity rules. Then review the DRS recommendations tab to see if the cluster returns to balanced state.
Limitations to plan for
Feature names, licensing editions, and default behaviors vary across vSphere major versions. Confirm DRS availability in your exact edition before designing around it.
Fully Automated DRS with an aggressive threshold can migrate latency-sensitive VMs at bad times. Use VM overrides to pin or soften automation for those workloads.
Licensing and edition entitlements for DRS have changed over time and should be verified against current Broadcom/VMware packaging for your deployment.
Close by choosing an automation level that matches operational maturity, set a moderate threshold and tune from observed migration history, keep affinity rules minimal and prefer should over must, and size the cluster for N+1 with headroom for vMotion.
 vsphere
0 replies
A thoughtful contribution can make all the difference. Be the first to share one.