Distributing Traffic with NGINX Upstream Load Balancing
Learn how to implement NGINX upstream load balancing to distribute traffic across multiple servers using Round Robin, weighted distribution, and session persistence.
17 May 2026, 12:36 UTC
Solving Backend Overload with Upstream Groups
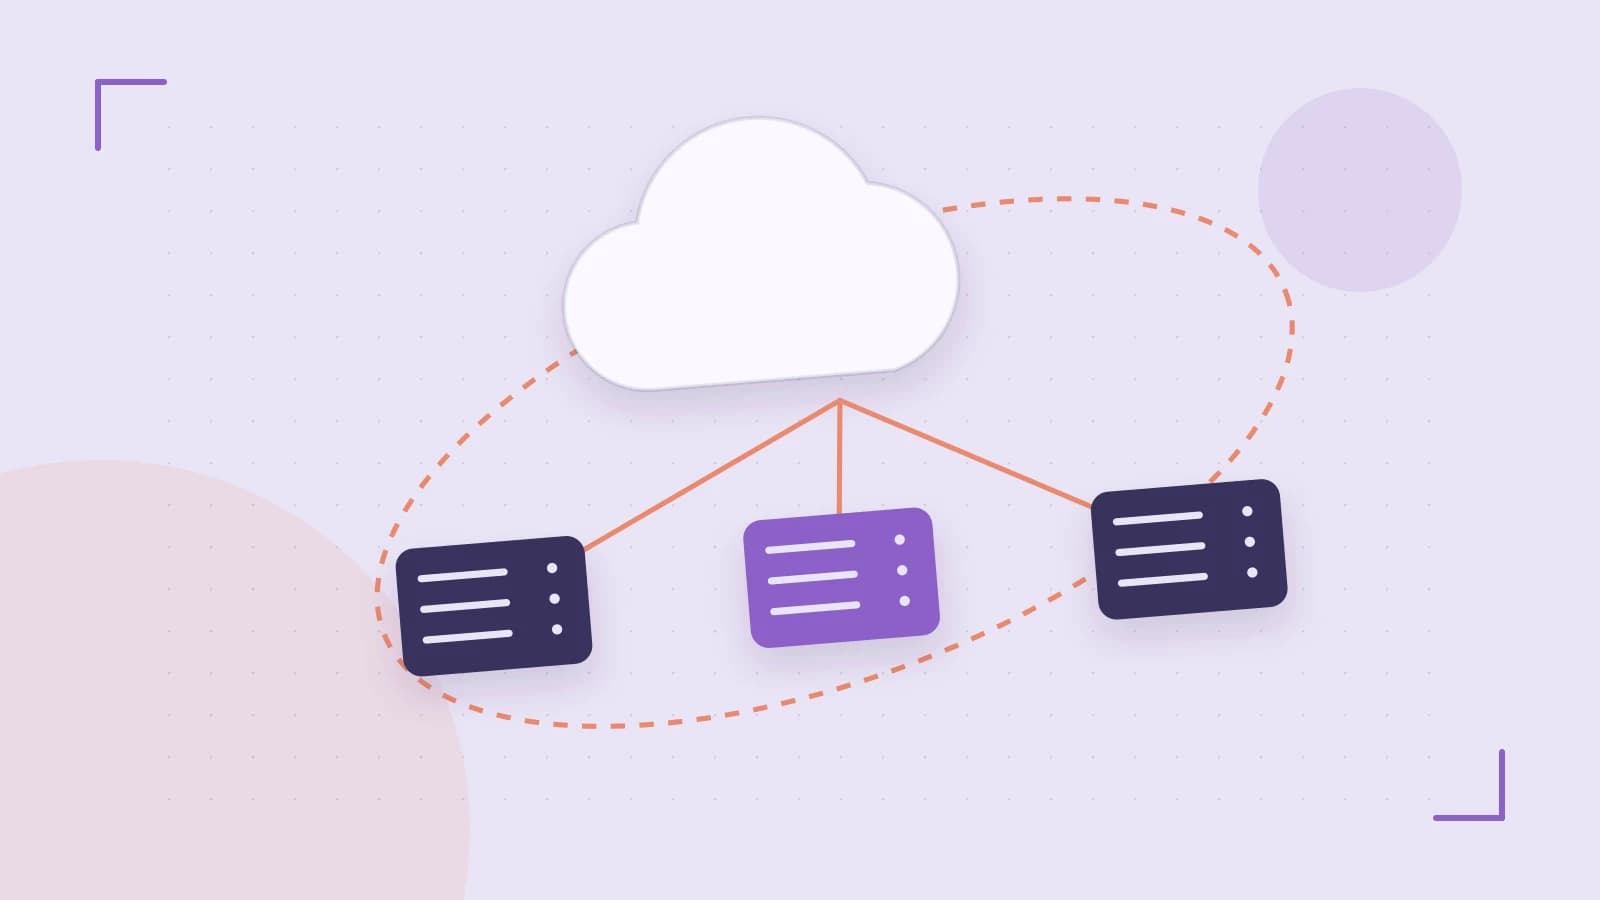
When a single application server reaches its CPU or memory limits, adding more hardware is the only way to scale. However, clients cannot be expected to track multiple server IP addresses. The solution is to use an NGINX upstream block, which creates a logical group of backend servers. NGINX acts as the single point of entry, distributing incoming requests across this group to prevent any single server from becoming a bottleneck.
The Mechanism: Upstream and Proxy Pass
The upstream module operates at Layer 7 (Application Layer). It defines a cluster of servers that NGINX treats as a single destination. The proxy_pass directive then tells NGINX to forward the request to that specific cluster rather than a single IP address.
By default, NGINX uses Round Robin, meaning it sends the first request to server A, the second to server B, and so on. This ensures an even distribution of load across identical hardware.
Worked Configuration Example
The following configuration demonstrates a weighted load balancer with basic health checks. This setup assumes NGINX is installed on a Linux distribution (e.g., Ubuntu or CentOS) and the user has sudo permissions to modify /etc/nginx/nginx.conf.
http {
    upstream backend_cluster {
        # Server 1 has higher capacity, receives more traffic
        server 10.0.0.10:8080 weight=3 max_fails=3 fail_timeout=30s;

        # Server 2 is a smaller instance
        server 10.0.0.11:8080 weight=1 max_fails=3 fail_timeout=30s;

        # Server 3 is a backup, used only if others are down
        server 10.0.0.12:8080 backup;
    }

    server {
        listen 80;
        server_name app.example.com;

        location / {
            proxy_pass http://backend_cluster;
            proxy_set_header Host $host;
            proxy_set_header X-Real-IP $remote_addr;
        }
    }
}
Configuration Breakdown
- weight: Tells NGINX to send a proportional amount of traffic to that server. In the example above, Server 1 receives 3 requests for every 1 request sent to Server 2.
- max_fails: The number of unsuccessful attempts to communicate with the server before it is marked as unavailable.
- fail_timeout: The duration the server remains marked as unavailable before NGINX attempts to send traffic to it again.
- backup: This server receives no traffic unless all other non-backup servers are unavailable.
Implementing Session Persistence
Round Robin is inefficient for applications that store session data locally on the server (e.g., local file-based sessions). To ensure a client always hits the same backend, replace the default method with ip_hash inside the upstream block:
upstream backend_cluster {
    ip_hash;
    server 10.0.0.10:8080;
    server 10.0.0.11:8080;
}
Operational Limits and Common Mistakes
Uneven Distribution with ip_hash: While ip_hash solves session problems, it can lead to "hot spots." If a large corporate office routes all its users through a single proxy IP, NGINX will send all those users to one backend server, potentially overloading it while others remain idle.
The "Slow Backend" Trap: If a backend server becomes slow (but doesn't crash), NGINX may continue sending requests to it, filling up the worker connection queue. To prevent this, always define proxy_connect_timeout and proxy_read_timeout within the location block to fail fast.
Configuration Reloads: Changes to the upstream block are not applied instantly. You must validate the syntax and reload the process.
# Run as root or with sudo
# 1. Validate syntax
sudo nginx -t

# 2. Reload configuration without dropping connections
sudo nginx -s reload
Verification and Diagnostics
To verify the load balancer is working, you can use a loop with curl to observe the responses from different backends (assuming your backends return their hostname or IP):
# Run from a client machine
for i in {1..6}; do curl http://app.example.com/; echo ""; done
If using Round Robin with two servers, you should see the responses alternate. To test the max_fails mechanism, stop the service on one backend server and monitor the NGINX error log: tail -f /var/log/nginx/error.log. You will see "upstream timed out" or "connection refused" messages followed by NGINX marking the server as unavailable.
 nginx
0 replies
A thoughtful contribution can make all the difference. Be the first to share one.