Airflow Dynamic Task Mapping: Runtime Fan-Out Without Static Workarounds
Static Airflow DAGs make data-dependent fan-out awkward. Dynamic Task Mapping expands tasks at runtime from upstream XCom values, but it changes visibility, retries, and scheduler load.
02 Mar 2026, 07:39 UTC
The problem: static DAGs, dynamic data
You write an Airflow DAG to process files landing in S3. Some days there are three partitions; other days there are thirty. Because Airflow parses DAG files to build a static task graph, you cannot simply write a loop over a list that does not exist yet and expect the scheduler to know about those tasks.
The usual workarounds are brittle. You might pre-generate a fixed pool of dummy tasks and skip unused ones, or trigger downstream DAGs with an external sensor. Both add noise and obscure the real dependency. SubDAGs attempted to solve this, but they are deprecated and carry known performance penalties.
Dynamic Task Mapping: expand at runtime
Dynamic Task Mapping, stable since Airflow 2.3, replaces those workarounds. Instead of defining a fixed number of downstream tasks, you call .expand() on an operator and pass an argument that resolves to an iterable at runtime—typically an XCom reference (Airflow's mechanism for passing small messages between tasks) from an upstream task.
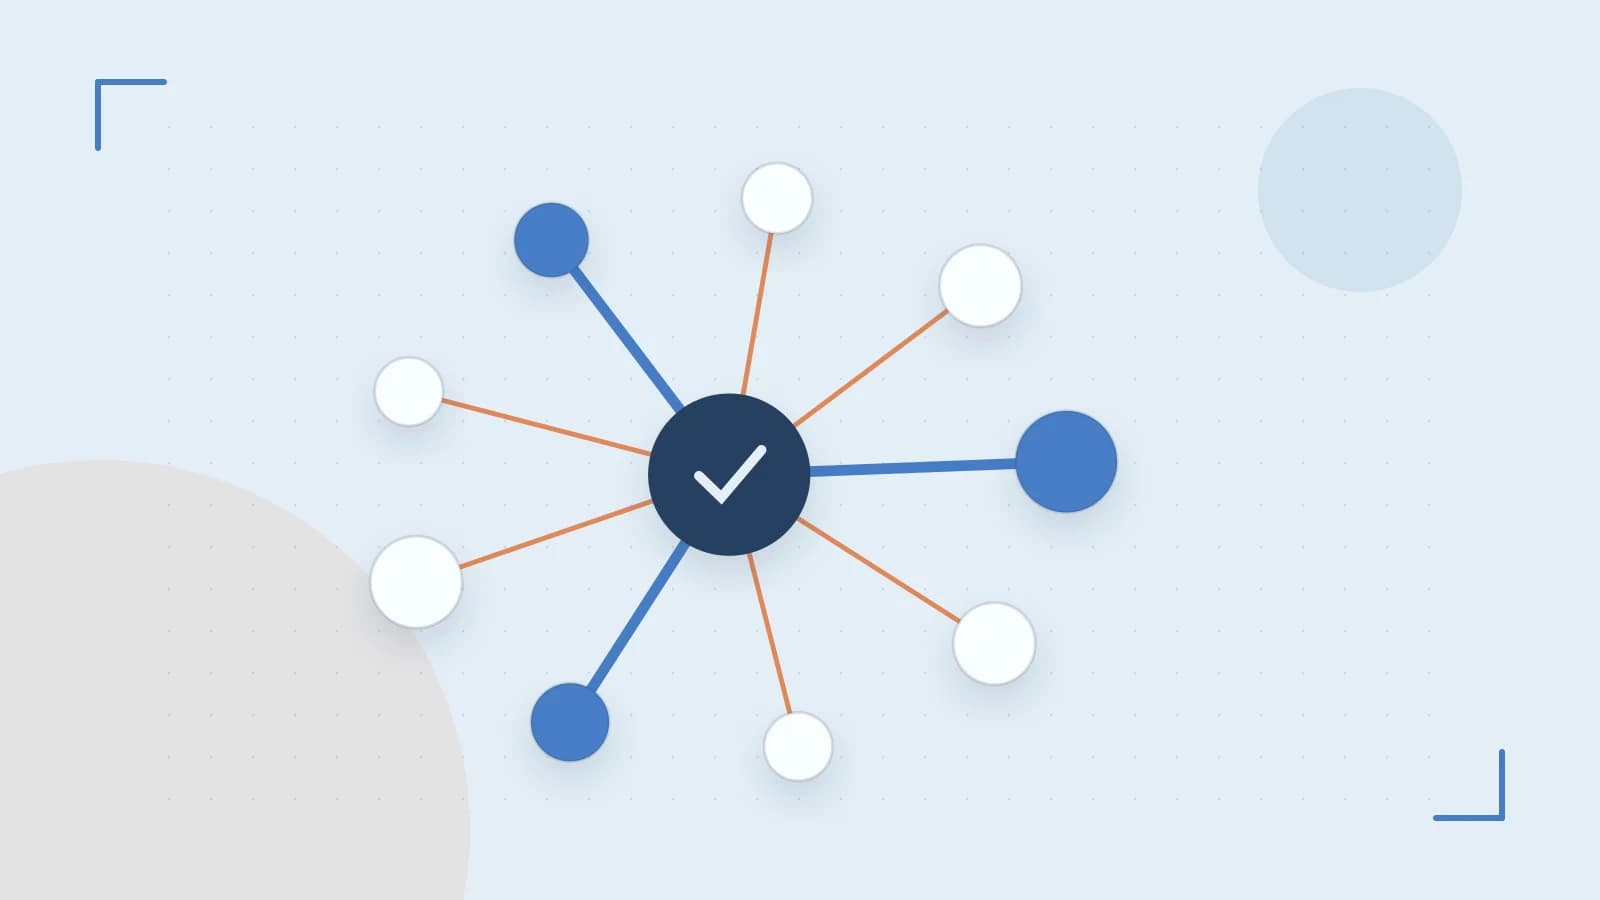
When the upstream task finishes and pushes its list, the scheduler creates one mapped task instance per element. Each instance runs independently, appears as its own row in the Grid view, and can succeed or fail on its own.
Static and dynamic parameters together
If some arguments should stay constant while others vary, use .partial() before .expand(). This locks static parameters and maps only the dynamic ones.
A worked example: partition processing
Suppose a fetch_partitions task discovers S3 prefixes, and a process_partition task handles each one.
from airflow.decorators import dag, task
from datetime import datetime

@dag(schedule_interval=None, start_date=datetime(2024, 1, 1), catchup=False)
def partition_pipeline():

    @task
    def fetch_partitions():
        # In a real DAG, this would query S3 or a metadata store
        return ["s3://bucket/data/2024-01-01/", "s3://bucket/data/2024-01-02/"]

    @task
    def process_partition(prefix: str, retries: int):
        # Process one prefix; each mapped instance gets its own prefix value
        print(f"Processing {prefix} with {retries} retries")

    partitions = fetch_partitions()
    # retries stays constant; prefix varies per mapped instance
    process_partition.partial(retries=2).expand(prefix=partitions)

dag = partition_pipeline()
Here, partitions is an XCom reference. The scheduler does not know how many process_partition instances will exist until fetch_partitions succeeds. If the task returns two prefixes, two mapped instances appear. If it returns thirty, thirty appear.
Verifying the upstream output first
Before triggering the full DAG, confirm the upstream task returns the iterable you expect. Run this in your Airflow CLI environment (a shell with Airflow installed and access to the metadata database):
airflow tasks test partition_pipeline fetch_partitions 2024-01-01T00:00:00You need read access to the DAG file and the metadata database. The command executes the task in isolation and prints the return value. If the output is not a list, tuple, or similar iterable, mapping will fail.
Trade-offs you must plan for
Dynamic mapping is powerful, but it changes operational behavior in ways that surprise teams migrating from static DAGs.
| Concern | What changes | Mitigation |
|---|---|---|
| Visibility | Mapped tasks do not exist in Graph or Grid views until the upstream task succeeds. | Alert on upstream task failure, not on missing mapped task counts. |
| Operator support | Not every core or provider operator supports .expand(). | Check operator documentation for your Airflow version before relying on it. |
| Scale | Large expansions increase scheduler and database load. | Set max_map_length in airflow.cfg to cap accidental massive fan-out. |
| Retries and SLAs | Each mapped instance retries and reports SLA misses independently. | Make downstream logic idempotent; do not assume group-level retry semantics. |
The scheduler load ceiling
If an upstream query accidentally returns one million rows, the scheduler will attempt to create one million task instances. The max_map_length setting (default varies by version; check your airflow.cfg) acts as a safety valve. Treat unbounded upstream outputs as a risk and add explicit limits in the producing task when possible.
When not to use it
If the set of tasks is known when you author the DAG, standard Task Groups or a Python loop in the DAG file remain clearer. Dynamic mapping shines when the fan-out is genuinely data-driven—file counts, API pagination, sharded database reads—and you cannot predict the cardinality at parse time.
Actionable checklist
- Run
airflow versionin your CLI to confirm you are on Airflow 2.3 or later; syntax and operator compatibility differ across releases. - Use
airflow tasks test <dag_id> <task_id> <execution_date>to verify the upstream task returns a clean iterable before mapping. - Trigger the DAG and inspect the Grid view. Confirm the number of mapped instances matches the upstream output length.
- Check scheduler logs for mapped task creation messages to validate expansion size.
- Review
max_map_lengthin yourairflow.cfgand adjust it to a sensible ceiling for your workload.
Dynamic Task Mapping removes the need for dummy tasks and external trigger hacks, but it trades static visibility for runtime flexibility. Use it when your data decides the shape of the workflow, and keep your upstream outputs bounded.
 apacheairflow
0 replies
A thoughtful contribution can make all the difference. Be the first to share one.